 Long-Context Serving
How Hyperscale LLM API Teams Architect KV Cache Management Under Real Throughput Pressure
Tiered KV caches only pay off when routing, I/O, and topology cooperate.
Priya Subramanian·
 Distributed Serving
NVMe Tier Bandwidth Accounting as the Primary Driver of Cost per Token in LLM Serving
NVMe bandwidth per token generated becomes the measure that governs LLM serving costs.
Priya Subramanian·
 Distributed Serving
Multi-Node Inference Cluster Network Topology for AI Workloads
Network topology for LLM inference must optimize KV cache movement across tiered storage.
Priya Subramanian·
 Distributed Serving
Storage Bandwidth Saturation Points That Collapse LLM Inference SLAs at Scale
Memory bandwidth becomes the binding constraint for long-context LLM inference at scale.
Priya Subramanian·
 Model-to-Hardware Fit
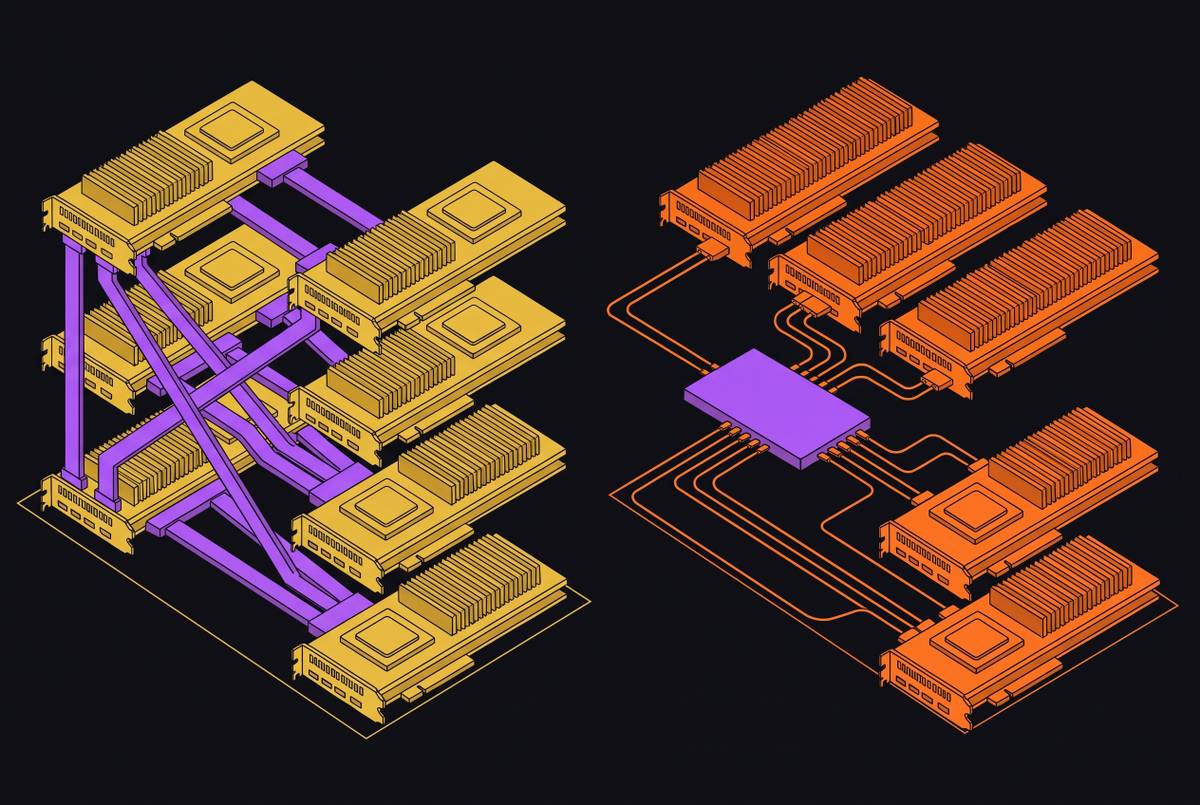
Qwen2.5 72B Tensor Parallelism Across NVLink vs PCIe GPU Topologies
NVLink keeps tensor parallelism fast; PCIe makes pipeline parallelism necessary.
Priya Subramanian·
 Model-to-Hardware Fit
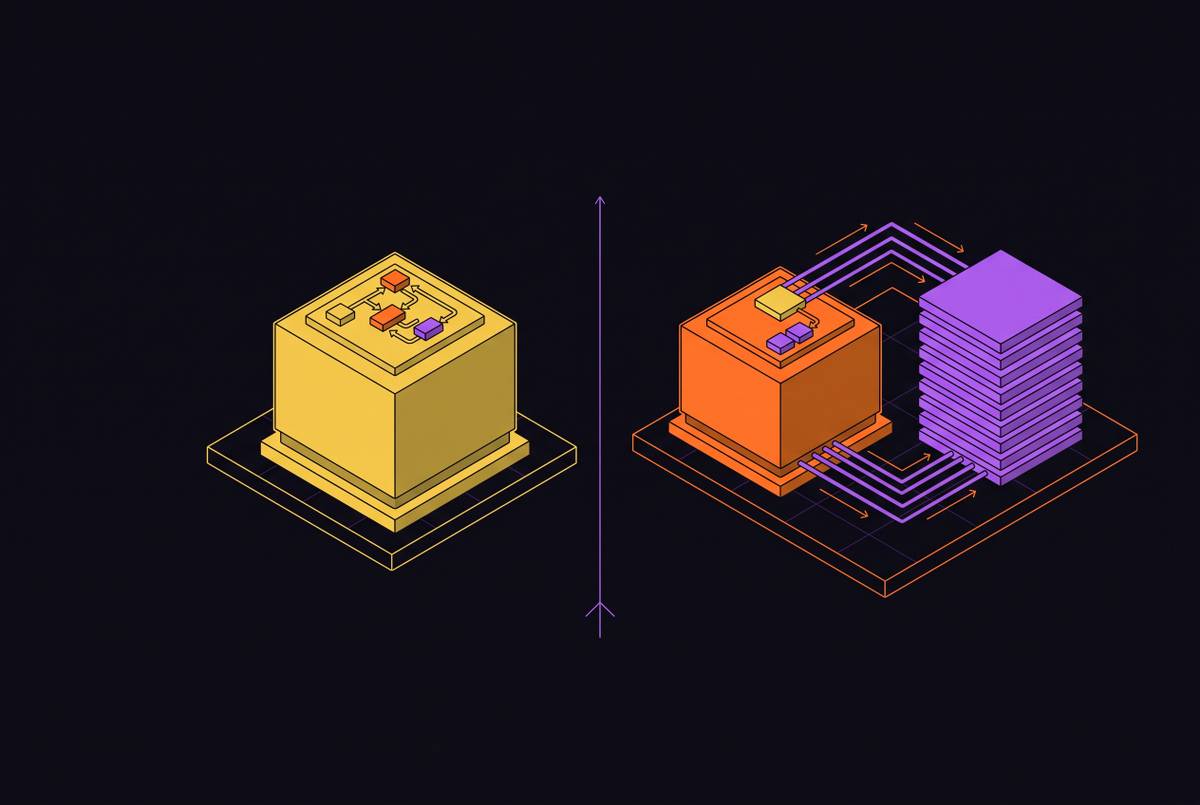
Llama 3 70B Serving on H100 vs A100 NVMe Offloading Configurations
H100's compute advantage shrinks dramatically when KV cache fills up.
Priya Subramanian·
 Model-to-Hardware Fit
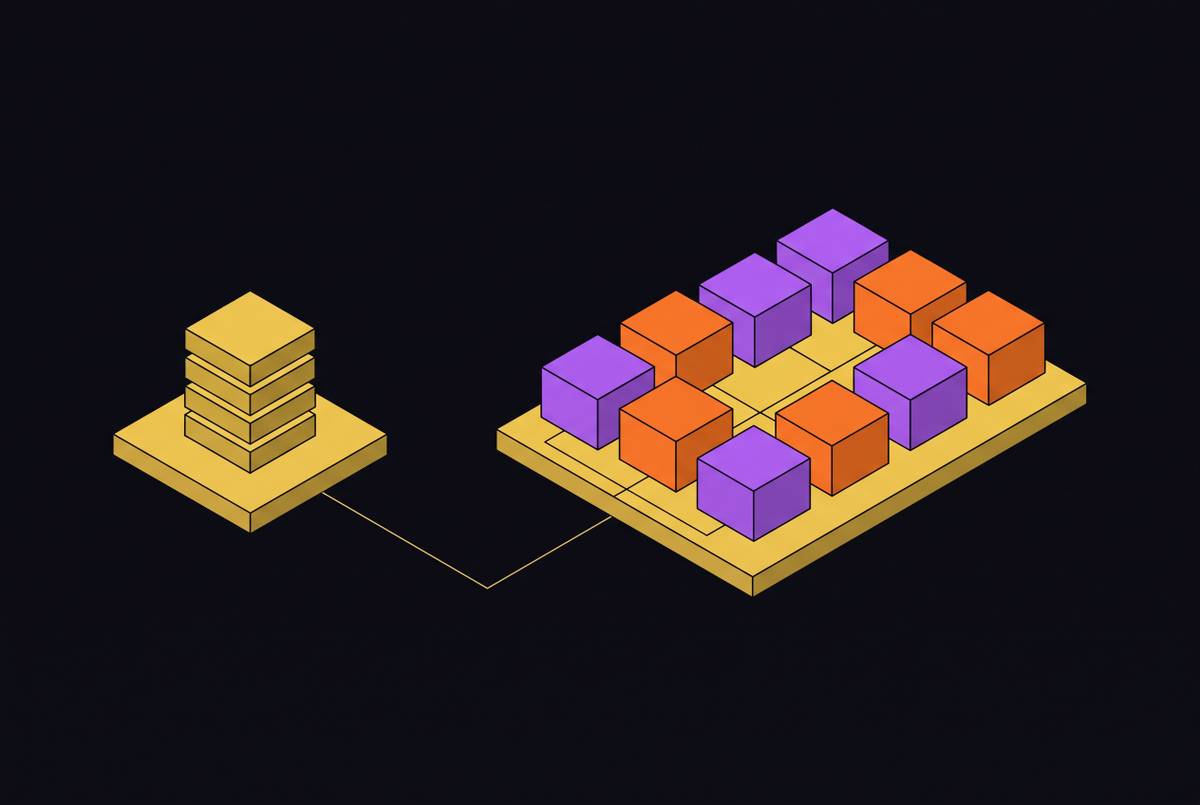
Mistral 7B and Mixtral 8x7B GPU Memory Footprint Comparison at Scale
Mixtral's sparse activation saves compute but demands full expert weights in VRAM.
Priya Subramanian·
 Benchmarking
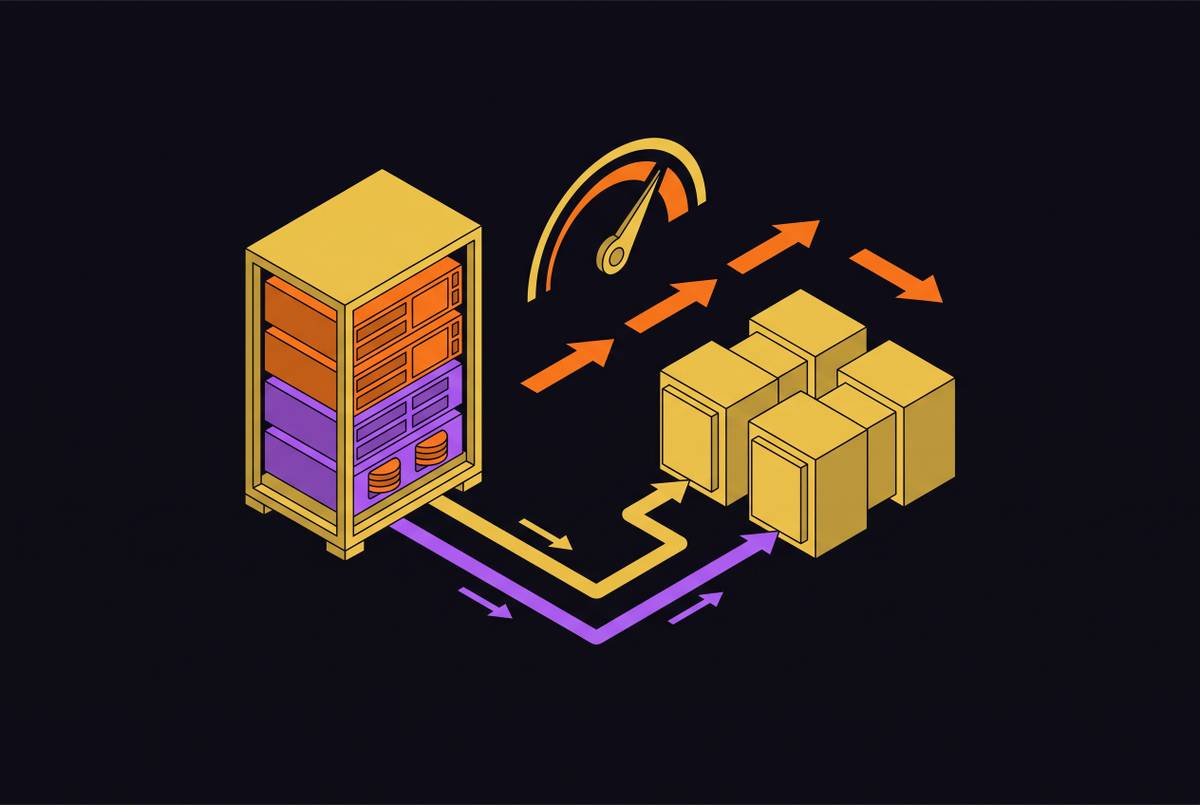
MLPerf Storage Benchmark Setup and Interpretation for AI Inference Workloads
A practical guide to running MLPerf Storage v3.0 for inference.
Priya Subramanian·
 Inference Runtime
TensorRT-LLM Paged KV Cache Configuration for Multi-LoRA Serving
How to allocate GPU memory efficiently when serving multiple LoRA adapters alongside KV cache.
Priya Subramanian·
 Inference Runtime
SGLang vs vLLM Throughput Under Long-Context Request Mixes
RadixAttention outpaces PagedAttention when workloads mix prompt lengths and reuse shared text.
Priya Subramanian·
 Features
vLLM PagedAttention Memory Allocation Under Concurrent Load
Precision format choice, not GPU count, determines long-context concurrency.
Priya Subramanian·