 Long-Context Serving
Cross-Request KV Cache Persistence Patterns for Session-Aware LLM Serving
Persisting KV state pays off only when fetching beats recomputing.
Darius Okonkwo·
 Long-Context Serving
Per-Request KV Cache Budget Enforcement as the Primary Cost Lever in Long-Context Serving
Capping KV memory per request is the biggest cost lever in long-context serving.
Mei-Ling Tsao·
 Long-Context Serving
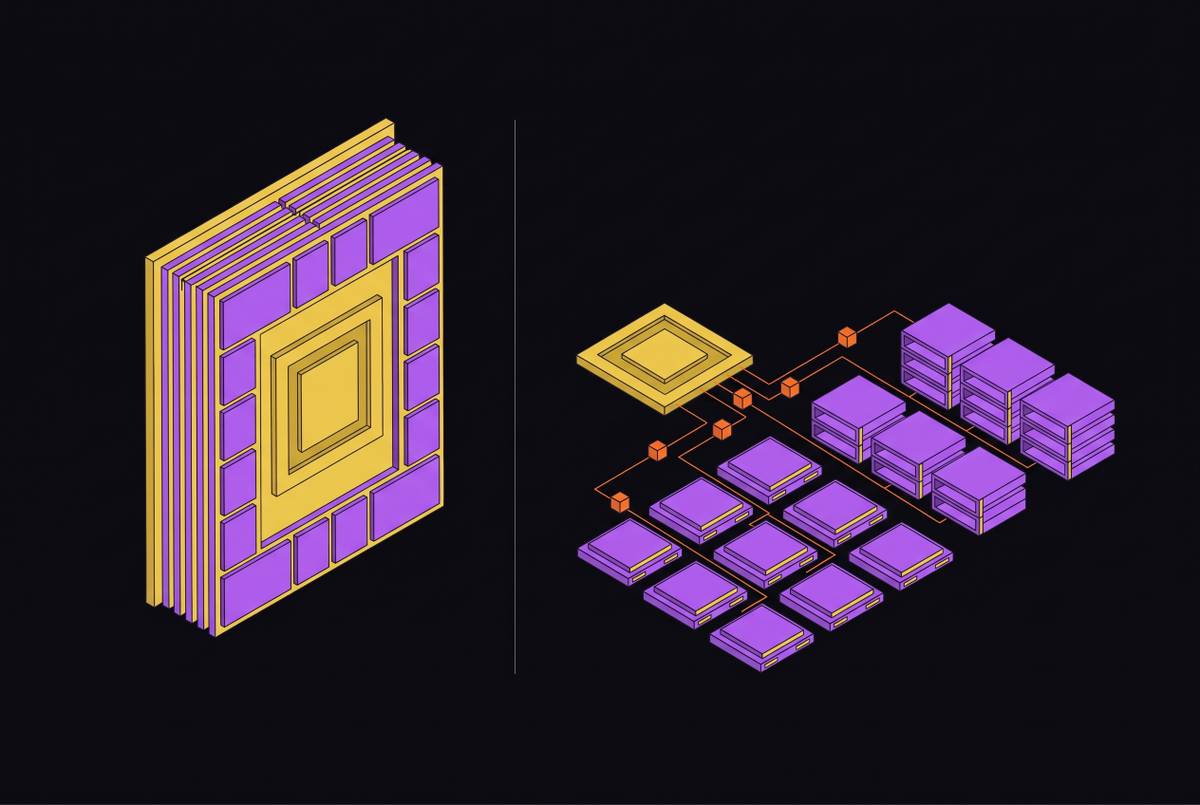
Disaggregated Storage Backends Versus Monolithic GPU Memory the Infrastructure Stack Vendors Are Actually Shipping
How vendors tier KV cache across HBM, DRAM, and NVMe.
Darius Okonkwo·
 Long-Context Serving
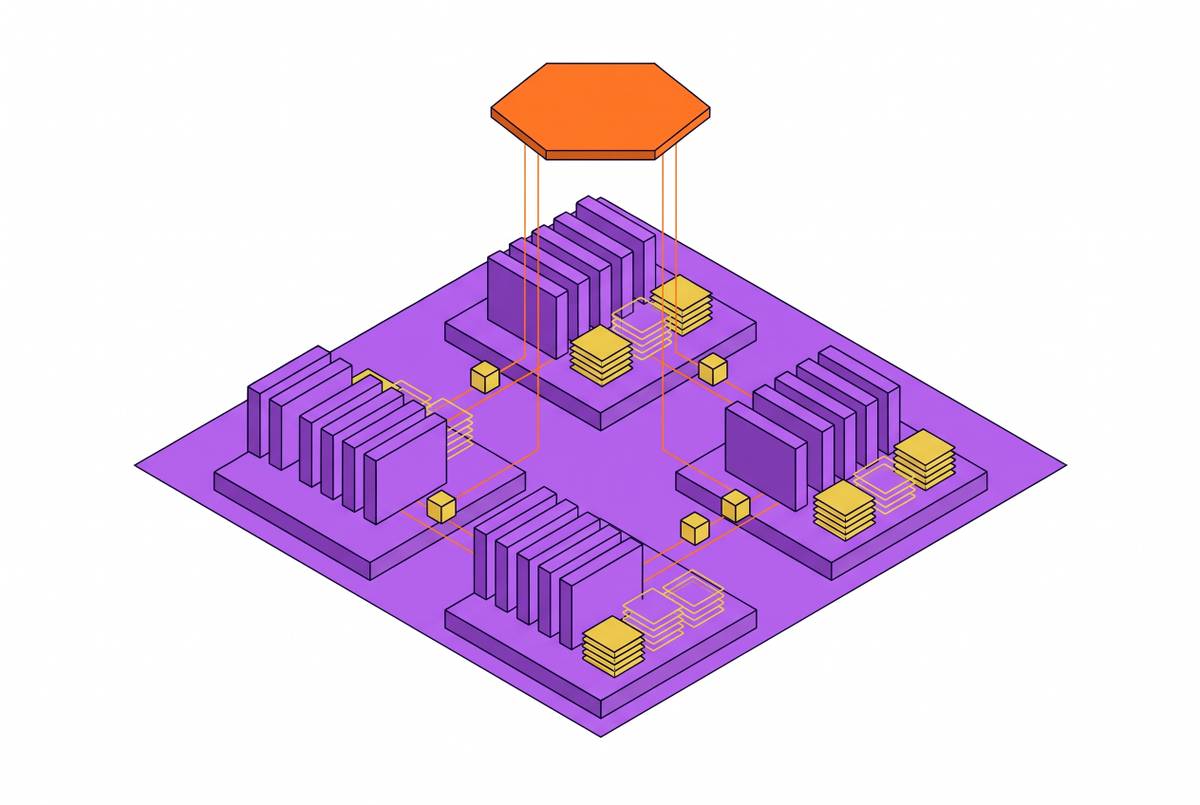
Distributed KV Cache Coordination Across GPU Node Boundaries in Multi-Host Inference Clusters
Cross-node KV reuse hinges on routing, metadata, and fast transfer.
Darius Okonkwo·
 Long-Context Serving
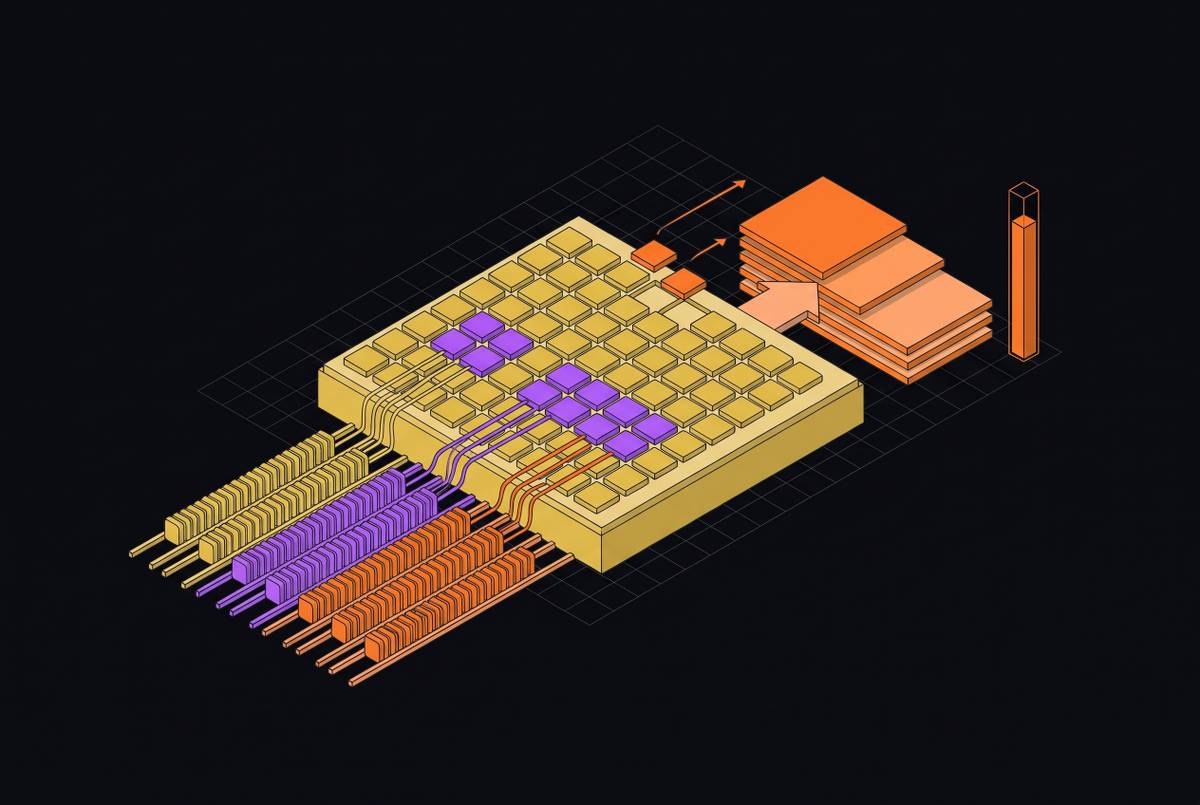
How Hyperscale LLM API Teams Architect KV Cache Management Under Real Throughput Pressure
Tiered KV caches only pay off when routing, I/O, and topology cooperate.
Priya Subramanian·
 Long-Context Serving
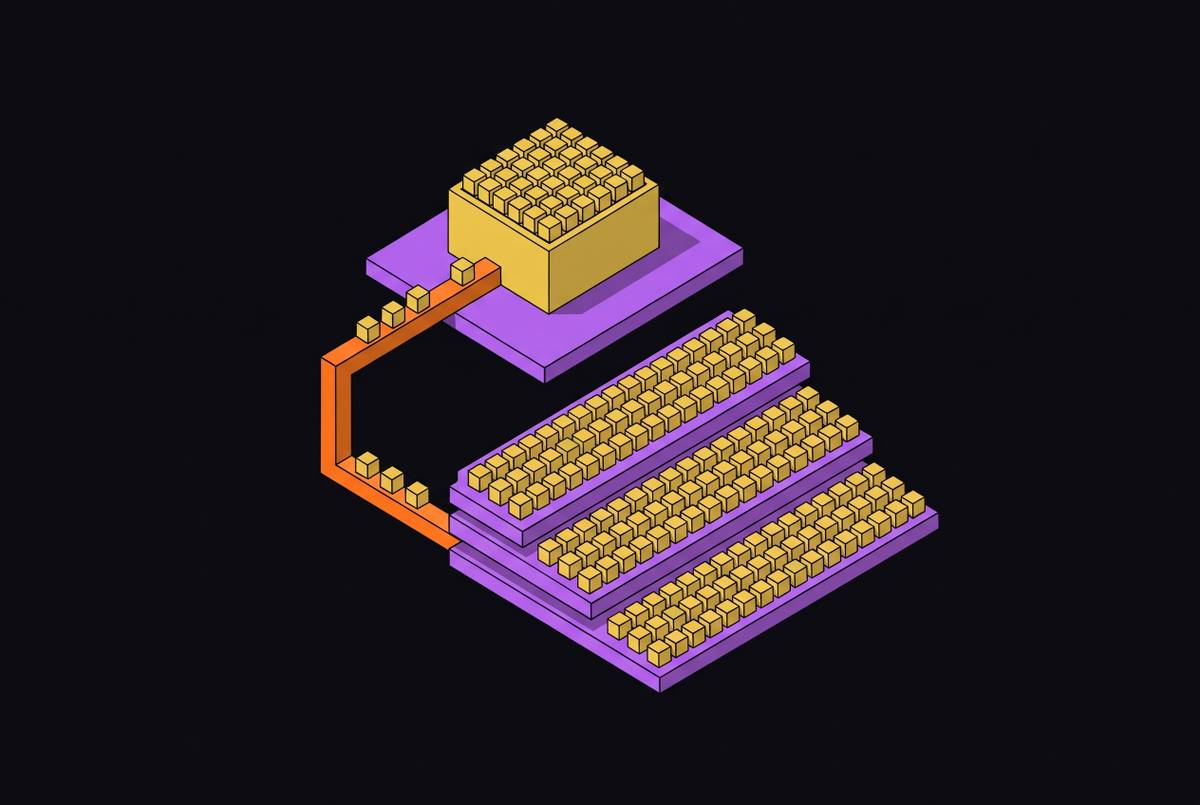
The Storage Layer Rethink That Unlocks Context Scaling Beyond What GPU Memory Can Offer
Long-context serving needs tiered KV cache storage, and PCIe is the real bottleneck.
Darius Okonkwo·
 Long-Context Serving
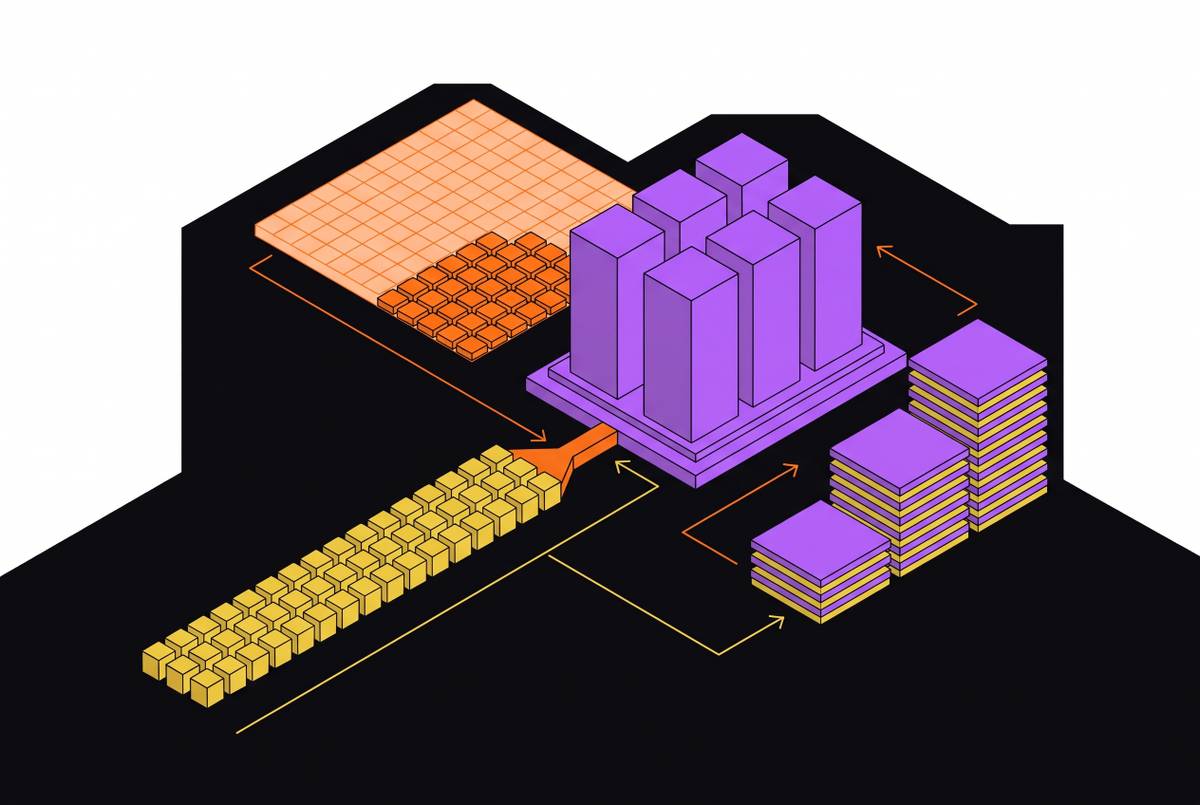
Beyond GPU Memory Walls the Hidden Bottlenecks Throttling Long-Context Transformer Deployments
GPU memory bandwidth, not capacity, becomes the real constraint for long-context model serving.
Mei-Ling Tsao·
 Long-Context Serving
Storage-First Architecture Decisions for LLM Serving Systems Targeting Million-Token Contexts
Organizing KV cache across memory tiers unlocks efficient million-token LLM serving.
Mei-Ling Tsao·
 Long-Context Serving
KV Cache Offloading Tools Ranked by Production Inference Overhead
Choose your KV offloading tool by workload: prefix reuse, agent sessions.
Darius Okonkwo·
 Long-Context Serving
KV Cache Storage Tiering Across DRAM HBM and SSD in Million-Token Serving Pipelines
Tiering KV cache across storage requires careful I/O engineering to beat recomputation costs.
Mei-Ling Tsao·
 Long-Context Serving
KV Cache Memory Pooling and Allocation Strategies for High-Throughput LLM Serving
Pooling and quantization strategies reclaim wasted GPU memory for higher concurrent LLM throughput.
Mei-Ling Tsao·
 Long-Context Serving
Why Long-Context LLM Serving Is a Storage Architecture Problem Before a Model Problem
KV cache storage, not model size, determines long-context serving capacity.
Darius Okonkwo·
 Long-Context Serving
Attention Kernel Efficiency at Long Sequence Lengths in Flash Attention 3
FlashAttention-3 reaches GPU compute limits on long sequences through asynchronous execution.
Mei-Ling Tsao·
 Long-Context Serving
Multi-Round Conversation State Management at Scale for Long Contexts
Managing KV cache across memory tiers prevents latency from becoming the bottleneck.
Tobias Wrenner·
 Long-Context Serving
Prefix Caching Effectiveness for Repeated Long System Prompts
Prefix caching saves latency only when matched KV blocks stay resident on GPU.
Darius Okonkwo·
 Long-Context Serving
Chunked Prefill Strategies for 128K Token Inputs in vLLM
Balancing GPU memory, cache capacity, and latency when processing prompts longer than 128K tokens.
Mei-Ling Tsao·
 Long-Context Serving
Disaggregated Prefill and Decode for Long-Context Request Handling
Separating prompt and token generation onto different hardware eliminates bottleneck conflicts.
Tobias Wrenner·
 Long-Context Serving
NVMe Offloading for KV Cache in Long-Context vLLM Deployments
NVMe offloading overcomes GPU memory limits for serving multiple long-context requests concurrently.
Darius Okonkwo·
 Long-Context Serving
KV Cache Memory Scaling From 32K to 1M Token Contexts
Tiered memory strategies keep long-context LLM inference tractable as token windows scale.
Darius Okonkwo·
 Long-Context Serving
KV Cache Compression Techniques for Long-Context LLM Serving
Quantization and pruning trade memory for speed in different ways depending on your workload.
Darius Okonkwo·