Prefix Caching Effectiveness for Repeated Long System Prompts
Prefix caching saves latency only when matched KV blocks stay resident on GPU.
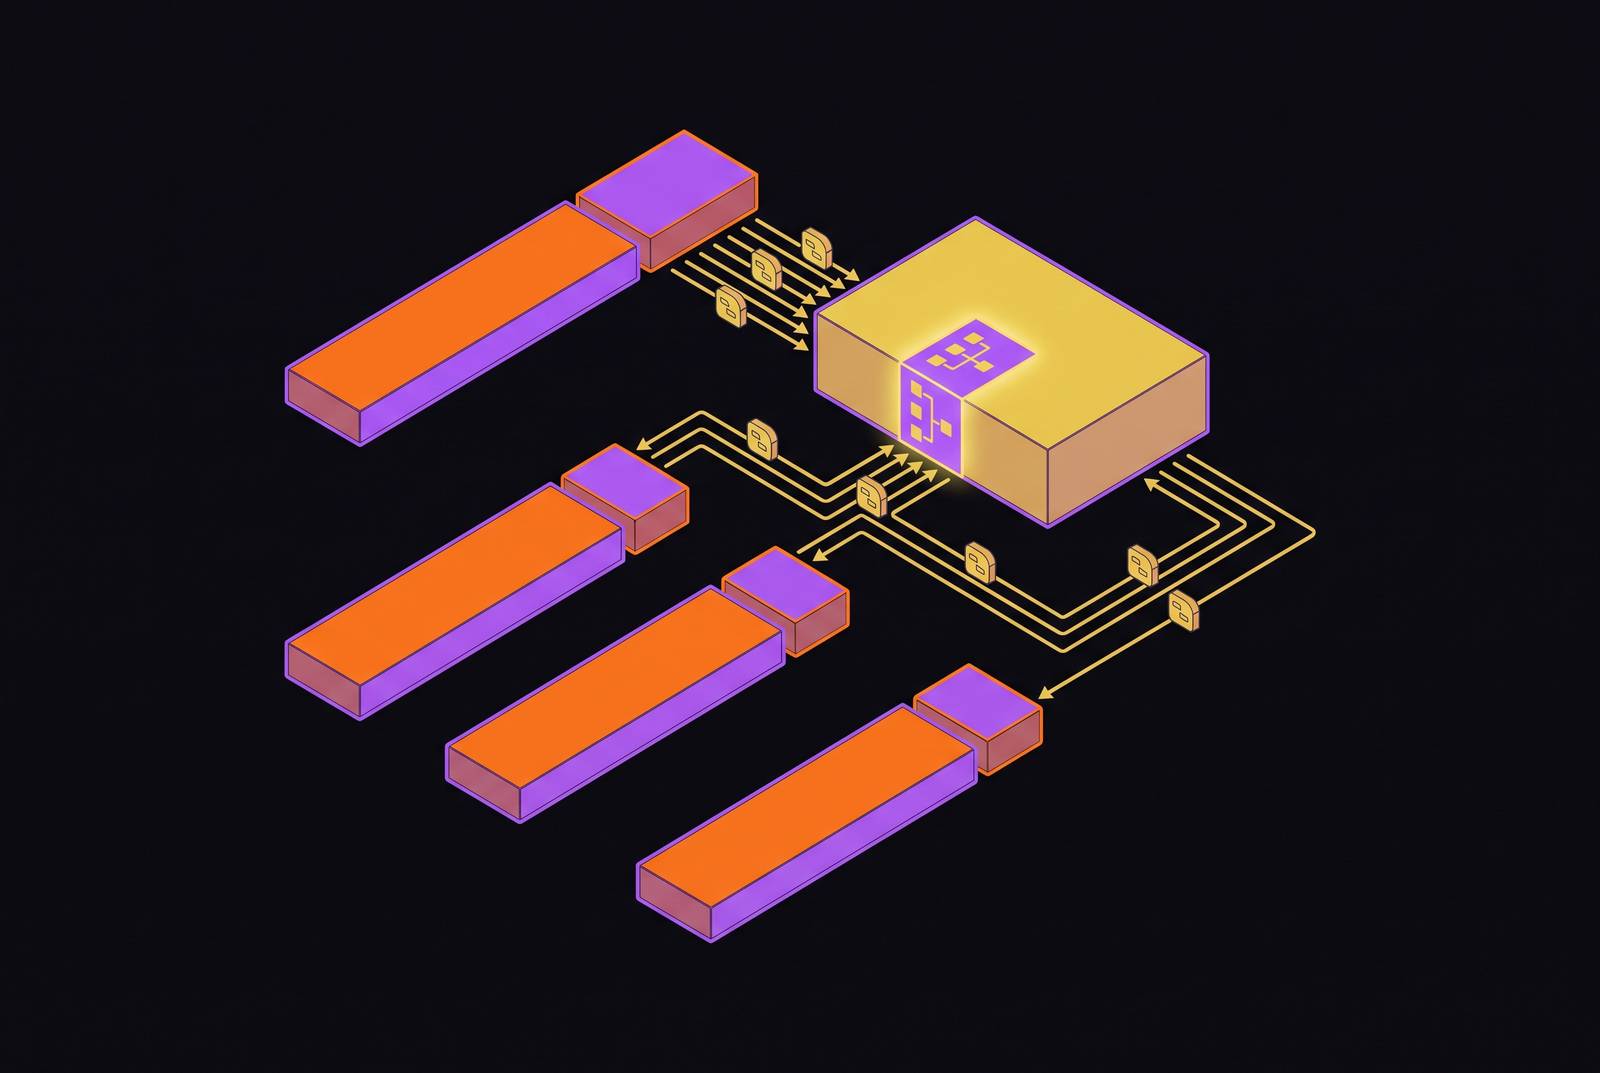
Long-context LLM serving needs exact prefix matching, GPU-resident KV blocks, cache-aware routing, and enough storage I/O bandwidth to recover blocks that spill. A cache hit saves prefill computation, but it cuts latency each time only if the serving system can reach those blocks without costly transfers.
Why repeated system prompts create a structural case for prefix caching
Repeated system prompts, tool definitions, and shared document context make up most of the tokens sent to an LLM agent on every call. Their repetition makes them the highest-leverage target for caching because the same input otherwise consumes GPU resources repeatedly. Without caching, every request recomputes the full attention pass over the shared prefix. The GPU time and memory bandwidth spent on that work produce no new information. At very long system prompts, prefill computation alone dominates time-to-first-token, or TTFT, making this repeated computation the specific cost prefix caching is designed to eliminate.
How prefix caching identifies and reuses matching KV blocks
Prefix caching replaces prefill computation with a lookup when incoming tokens exactly match a previously computed prefix. vLLM's Automatic Prefix Caching hashes incoming prompt prefixes and reuses KV blocks when those hashes match. SGLang's RadixAttention instead organizes the cache as a radix tree, which handles requests that share a prefix before branching into different continuations. The system computes new tensors only for the suffix tokens.
Matching is deterministic, so identical byte sequences produce identical hashes. Requests with the same system prompt and prefix can thus reuse the same cached blocks if those blocks stay resident, and vLLM's APC works without changes to the application, both across requests in the same batch and across batches when the cache is warm. SGLang's tree structure fits branching patterns such as Monte Carlo decoding and multi-path agent loops. That fit helps with these workloads, but the matching structure alone cannot ensure that a distributed serving system sends the request to the place that holds its cache.
When a prefix hit actually saves time: VRAM residency as the gating condition
The effectively free hit requires the matched KV blocks to be resident in GPU HBM when the request arrives. H100 SXM5 HBM provides roughly 3.35 TB/s of bandwidth, compared with roughly 63 GB/s for CPU DRAM transfers via PCIe 5.0 and roughly 7 GB/s for NVMe SSD transfers via PCIe 4.0. If the matched blocks are absent from VRAM, the system faces a reload or recomputation.
William Meng, Benjamin Lee, and Hong Wang report that PCIe transfers account for 99% of observed latency in the KV cache offloading scenarios they study. Yet model weights and activations occupy most VRAM, while large models at long context can require tens of gigabytes of fully resident KV cache. vLLM's PagedAttention reduces fragmentation waste to a small fraction, making useful prefix residency possible within that remaining space. Stable system prompts and tool definitions can sustain high reuse, but their latency advantage lasts only while the relevant blocks stay warm.
How scheduling decides whether a cache hit is possible at all
In a multi-node cluster, a request must be routed to the node holding its resident blocks to reach them. Cache-affinity scheduling sends requests with the same prefixes to the same node so that more of them can reuse the cache. However, popular prefixes can turn those nodes into hotspots while others sit idle. Least-loaded scheduling addresses the imbalance but scatters shared-prefix requests across nodes, reducing their chance of finding a warm cache. Perfect memory management on one GPU cannot compensate for a request routed elsewhere.
DualMap, published at ICLR 2026, identifies this conflict in prior schedulers, including Mooncake, Preble, and NVIDIA Dynamo, which operate within a single mapping space. It maps each request to two candidate nodes through independent hash functions and selects the better candidate using current system state. Its SLO-aware routing switches from cache affinity to load awareness when TTFT exceeds the SLO, while hotspot-aware rebalancing migrates requests from overloaded nodes. A dual-hash-ring lets the system scale its instances quickly. DualMap reports that it can handle up to 2.25× as many requests under the same TTFT SLO constraints as state-of-the-art work.
Despite this significant advance, affinity and balance remain in conflict whenever preserving reuse concentrates demand on limited compute capacity. Explicit residency management, including the GPU-memory and NVMe tier managed by Open Lake, needs routing affinity so that requests can keep using hot blocks. Systems that pair scheduling with residency management can keep frequently reused prefixes on the GPU tier that reaches them fastest.
Tiered storage and RDMA as the fallback when VRAM runs out
When warm prefixes exceed GPU capacity, tiered storage exchanges reload latency for additional space. The practical hierarchy places hot blocks in GPU HBM, warm blocks in CPU DRAM, and cold blocks on NVMe SSDs. The bandwidth gap means that these tiers cannot be treated as equivalent cache capacity. A fallback is useful only when retrieving stored KV costs less than recomputing it. Open Lake's KV cache management system uses storage bandwidth and capacity to decide which blocks stay hot in GPU memory and which spill to NVMe.
Mooncake, from Moonshot AI / Kimi and presented at USENIX FAST '25, treats KV cache as a disaggregated resource across cluster-wide CPU DRAM and SSDs. Its transfers can move only as fast as the RDMA bandwidth per NIC allows, even with multiple high-bandwidth links across nodes. NVIDIA NIXL moves KV tensors between prefill and decode GPUs over RDMA or NVMe at wire speed, supporting disaggregated prefill-decode serving. NVIDIA ICMSP, announced at CES 2026, uses BlueField-4 DPUs to move KV cache off the GPU compute path. These mechanisms address movement, but they do not remove the bandwidth constraint.
LMCache provides an independent management layer that persists and shares blocks across sessions, restarts, and server instances. Its backends include Redis, local disk, S3-compatible storage, Mooncake, and InfiniStore, with APIs for locating, moving, pinning, and compressing blocks. Ray et al. in 2026 propose treating KV management as a content-distribution problem across datacenter and cloud boundaries, including standard internet links when recomputation costs more than transfer. DualPath targets storage bandwidth in disaggregated agentic inference and reports up to 1.87× higher offline throughput and 1.96× higher online agent runs per second. These approaches, along with Open Lake's NVMe-at-scale work, make storage I/O a core part of serving as well as part of the cache.
Compression strategies that expand what fits in each tier
Compression expands the useful capacity of every tier by reducing the footprint of each KV block. Switching from BF16 to FP8 KV storage halves cache memory, while NVFP4 reduces it further. Smaller blocks also reduce the volume that must cross an RDMA link or return from NVMe. DeepSeek's latent attention architecture, MLA, provides approximately 5–28× architectural compression depending on the MHA baseline. With FP8 quantization at 2× and prefix caching at 5–12× on hit, those reductions make it possible to use million-token contexts in production, though each gain has its own conditions.
The decisive distinction is whether compression preserves reusable representations. Lossy methods including H2O, SnapKV, and KIVI 2-bit quantization can alter token representations in ways that invalidate the exact-match hashing used for prefix reuse. Teams applying those methods without separate uncompressed prefix stores can see hit rates collapse even as memory use falls. SplitZip, introduced in 2026, instead uses ultra-fast lossless KV compression as a transport primitive for disaggregated serving, preserving hash-based matching. Open Lake's emphasis on BF16 and AI-native compression belongs to this engineering choice, where preserving reuse matters as much as shrinking storage. A smaller cache is not an improvement if its contents can no longer serve the repeated prefix.
Where agentic workloads break the standard prefix caching model
Standard prefix caching assumes that prompts arrive once and the cache grows append-only. Agentic workloads violate that assumption through two distinct changes, namely position shifts and deliberate mutation. In multi-turn loops, new tool outputs can move content seen before to different absolute positions. Exact-prefix matching cannot recover those shifted chunks even when they have the same content. An agent may also need to remove a failed tool call or replace stale content without recomputing everything that comes after it. These are different problems because finding reusable content does not provide a primitive for editing it.
Irminsul, introduced in 2026, addresses position-independent caching for MLA-based agentic serving. It targets the mismatch between standard prefix hashing, which assumes MHA-style position-encoded keys, and compressed MLA representations. Leyline, also introduced in 2026, addresses policy-driven mutation through a declarative (span, replacement) 4-tuple. Its per-architecture kernel restores position correctness through a closed-form correction to positional rotations without full re-prefill, and the work is validated on SGLang. Without such support, production agentic harnesses fall back to full re-prefill on edits.
Agent loops also stress scheduling and eviction even when content remains reusable. CacheWise's 2026 study of real coding agent traces finds that FCFS batching and LRU eviction cause thrashing because they ignore session prefix overlap and tool-call timing. Its prefix-aware scheduling and reuse-aware eviction reduce evictions by up to 2–2.6× and improve total agent session completion time by up to roughly 3.5×. Position-aware addressing, explicit editing, and reuse-aware eviction remain active engineering requirements rather than properties that standard prefix caching supplies automatically.
The security boundary that cache hit rates create
Shared prefix caches also create a timing boundary between tenants. NVIDIA's developer documentation warns that timing differences from KV reuse can let one tenant infer whether another tenant's prompt prefix is cached. Greater sharing makes that signal more measurable, so improved hit rates carry a non-performance cost. Mitigations include separate per-tenant cache namespaces or disabling prefix caching for sensitive workloads. Single-tenant and on-premises deployments running open-source models such as Llama, Qwen, or Mixtral are largely unaffected by this cross-tenant concern, making isolation a deployment decision.
Reading hit rate data honestly: what the numbers tell operators and what they obscure
A high hash-matching hit rate in a warm vLLM APC workload does not distinguish a VRAM hit from a CPU DRAM or NVMe reload. It therefore proves that prefixes match. A high hit rate with a wide TTFT distribution points to tier-level misses. For very long system prompts, this distinction matters most because skipping prefill saves the most time.
Measurements across sessions can also hide what changes within each one. As sessions grow longer, the conversation history changes the context after the stable prefix, which limits how much can be reused. Position shifts and policy-driven edits can make agentic hit rates understate the amount of repeated content. Lossy compression can make hit rates fall in a similar way for a different reason, while poor routing can send requests away from blocks that are still resident. Each cause needs its own fix, even when the overall hit rate looks the same.
The diagnostic approach is to measure hits separately for VRAM, DRAM, and NVMe, track them per session, and correlate them with the TTFT distribution. Open Lake's storage-layer instrumentation and NVMe-at-scale work provide one option for distinguishing those cases in production. Teams serving Llama, Qwen, or Mixtral at scale need visibility into where matched blocks are found.
Sources
- CacheWise: Understanding Workloads and Optimizing KVCache Management for Efficiently Serving LLM Coding Agents
- Understanding Bottlenecks for Efficiently Serving LLM Inference With KV Offloading
- Leyline: KV Cache Directives for Agentic Inference
- DualMap: Enabling Both Cache Affinity and Load Balancing for Distributed LLM Serving
- An Internet for the KV Cache: Rethinking Classical Infrastructure Boundaries in the LLM Inference Age
- Compute Or Load KV Cache? Why Not Both?
- LMCache: An Efficient KV Cache Layer for Enterprise-Scale LLM Inference