Measuring Time-to-First-Token and Inter-Token Latency Under Sustained Load
Understanding how prefill and decode phases behave separately under server load.
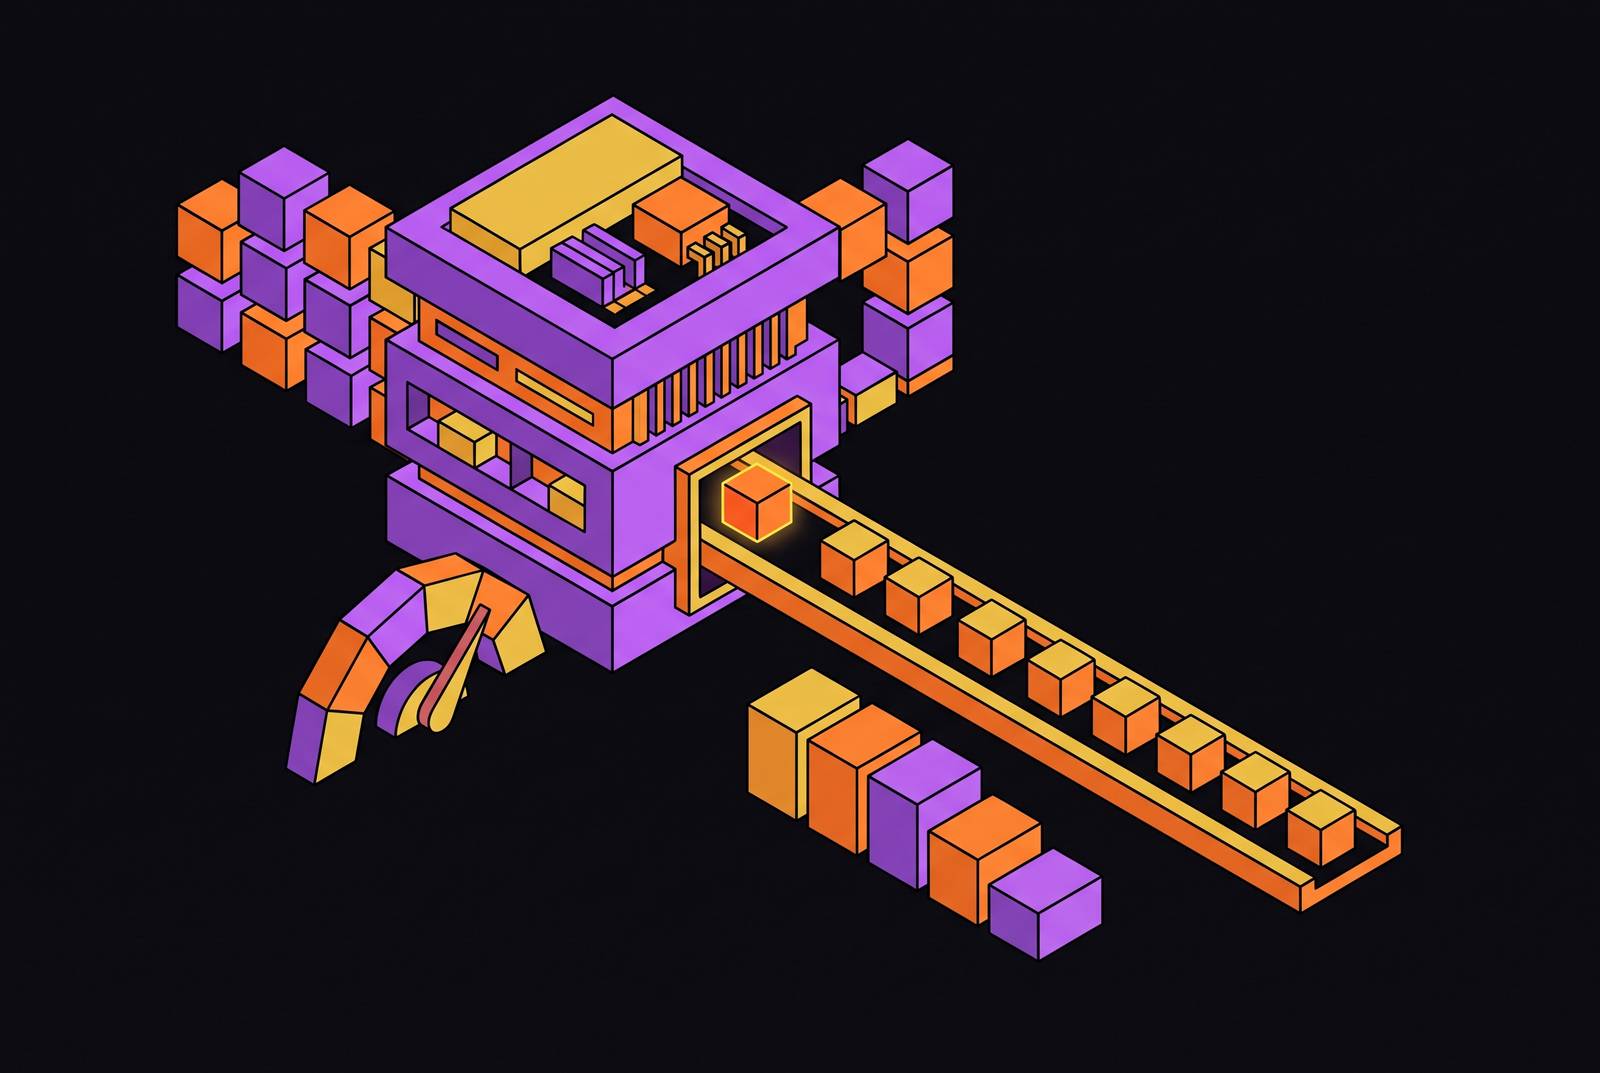
LLM inference splits into two mechanically distinct phases: prefill and decode, and that split explains every measurement problem that appears once a server is under real load. Prefill reads the entire prompt at once, runs compute-bound, and builds the KV cache along the way. Time-to-first-token captures exactly that phase. Decode works differently: it produces one token per step, and each step has to read the full KV cache back out of memory. That makes decode bound by memory bandwidth rather than compute, and it's what inter-token latency and time-per-output-token actually measure.
End-to-end latency works out to TTFT plus (output tokens minus one) times TPOT, in ClickHouse's formulation, and neither metric alone is sufficient. A request with a fast first token and a merely average per-token pace can still run long once output length climbs. Neither metric alone settles whether a serving stack is fast. OpenTelemetry's GenAI semantic conventions treat both as histograms rather than single numbers (gen_ai.server.time_to_first_token, gen_ai.server.time_per_output_token), and vLLM's own Prometheus histograms span four orders of magnitude in their bucket ranges. That range reflects how wide the real spread gets even before concurrent requests enter the picture, not an accident of instrumentation design.
Under concurrency, prefill from new arrivals competes with decode of in-flight requests for the same GPU resources, a phenomenon called prefill-decode interference. Even without any of that competition, TTFT already depends on how long the prompt is: a short chat message and a lengthy document produce very different first-token waits on identical hardware and an identical model. A "good TTFT" is a curve that shifts with input shape, not a fixed number to hit. It's a curve that shifts with input shape, and any benchmark that reports a single TTFT figure without stating prompt length is reporting an incomplete answer.
What single-request benchmarks cannot measure
Sending one request at a time and reporting the mean latency tells an accurate story about an idle server and very little about anything else. Google's own SRE guidance warns that a simple average can obscure tail latencies. Serving benchmarks lean on P50, P95, and P99 instead of a single mean. The AIMulitple benchmark from August 2026 shows how far the tail can drift from the median: MiniMax's coding-task results moved from a moderate median latency to a much higher P90 because how long it spends "thinking" varies request to request, making outcomes both slower on average and far less predictable. That spread sits entirely outside the P50 window, which happens to be where most vendor benchmarks stop reporting.
A concrete case makes the failure mode impossible to wave away. Because the fixture doesn't actually generate variable-length output, its end-to-end request duration cannot substantiate time to first token, inter-token latency, sustained token throughput, or resource sizing, in the issue's own language. That isn't a one-off bug in an obscure test harness. The relevant GitHub issue, #1230 in the NVIDIA/nvcf repository, is dated August 26, 2026. It's the standard shape of a synthetic benchmark that was never built to reflect real generation workloads in the first place, and it shipped from a team building serving infrastructure at scale.
The acceptance criteria written into that issue spell out what a real measurement requires: workload identity, request shape, concurrency, duration, token accounting, CPU and memory sampling during steady state, and explicit separation of recovery intervals from steady-state measurements. InferenceBench, published on arXiv in May 2026, arrives at a similar conclusion from a different angle. It treats prefill latency, decode latency, and concurrent request throughput as three separate optimization targets precisely because no single number captures all three, and it builds in an integrity gate to screen out reward-hacking tactics, pre-generated text, model substitution, and similar tricks that inflate a benchmark score without reflecting how the system behaves under genuine serving conditions.
Queuing, prefill-decode interference, and KV cache pressure under load
Sustained concurrency doesn't degrade TTFT and ITL evenly. Three distinct mechanisms drive the degradation, and each compounds the others rather than acting alone.
Queuing is the most direct. New requests wait behind whatever prefill and decode work is already running, and that wait adds straight to TTFT regardless of how capable the model or the hardware is underneath it.
Prefill-decode interference grows more severe as batch size increases. Bigger batches raise aggregate throughput, but the gain isn't free: it comes at the cost of consistency for any individual request. Continuous batching, measured originally in the Orca system, stands as one of the largest throughput levers available to a serving stack, but IntuitionLabs' framing is careful to note that the throughput win trades away per-request latency predictability in exchange for server-wide efficiency. IntuitionLabs reports that continuous batching, introduced in the Orca paper, achieved a 36.9x throughput gain over static batching at matched latency. Lyceum Technology's analysis puts the tradeoff in blunter terms: push batch size too high and overall system throughput climbs while individual request latency spikes to levels that real-time applications can't tolerate. Batch size has to be checked against a latency service-level objective before it's set, not treated as a dial to crank toward maximum throughput.
KV cache pressure is the mechanism single-request testing is least equipped to catch, and it's the one that matters most once a server is running at real concurrency. The cache grows linearly with context length, and at long enough contexts a single large request can eat nearly all the GPU memory headroom left over once model weights are loaded. When the cache overflows GPU HBM, the serving system must either evict to CPU DRAM or NVMe or recompute the missing portion, and both options degrade ITL directly and delay TTFT for subsequent requests. Digital Applied's 2026 engineering guide shows where this problem becomes structural rather than occasional: on a large Llama baseline at extreme context lengths, KV cache memory closes in on the same order of magnitude as the model's own parameter memory. Past that point, the bottleneck isn't compute anymore, it's memory movement, and every optimization decision downstream of that point has to follow the memory rather than the arithmetic.
None of these three mechanisms stays contained to its own lane. Queuing raises the number of concurrent requests contending for KV cache space. Cache pressure then forces eviction or recomputation, which stretches out decode steps. Queuing increases the number of concurrent requests competing for KV cache space, cache pressure forces eviction or recomputation that lengthens decode steps, and longer decode steps delay prefill for new arrivals, increasing queue depth further. The loop closes on itself, and that closed loop is the actual definition of what "under load" means for these two metrics: not simply more traffic, but a feedback cycle that single-request testing structurally cannot trigger.
The three-tier memory hierarchy and KV cache pressure
Where a given piece of KV cache data physically sits at any moment decides whether ITL stays flat or swings wildly once load picks up. Production serving stacks manage this with a three-tier hierarchy: hot cache lives in GPU HBM, warm cache spills to CPU DRAM, cold cache lands on local NVMe, and shared or persistent state can sit on network storage, coordinated by caching layers such as LMCache.
Recomputing a prefill from scratch used to be the default fallback when cache wasn't available. At 2026 context lengths, that assumption has flipped: storing the cache and reloading it from NVMe is now routinely faster and cheaper than recomputing it, a real change from how earlier serving systems were designed. That shift pulls NVMe directly into the critical path for ITL rather than leaving it as a cold-storage afterthought. KV cache traffic against that storage is continuous and write-heavy, requiring datacenter-grade drives rated at 1-3 drive-writes-per-day, spread across multiple drives for bandwidth. Generous DRAM, on the order of one to two terabytes, paired with multiple high-endurance NVMe drives, has become a standard line item on the inference bill of materials rather than an optional upgrade for teams anticipating heavy load.
The consequence for measurement follows directly from that infrastructure reality. A benchmark that fits its entire working set comfortably inside GPU HBM never forces a cache spill, so it cannot observe the latency degradation that emerges when real concurrency forces cache spills. That's the same blind spot the single-request benchmarks carried earlier in this piece, just relocated to the storage layer instead of the queuing layer: a test that never stresses the memory hierarchy can't report on what happens when that hierarchy gets stressed. A sustained-load benchmark has to be sized deliberately to exhaust GPU HBM headroom at the target concurrency level, or the DRAM and NVMe tiers never get exercised and the resulting numbers describe a condition production will never actually be in.
Quantization, the KV cache memory budget, and the measurement baseline
Quantizing the KV cache changes two things at once: how much memory the cache needs, and how accurate the attention computation built on top of it stays. Both effects land on latency numbers gathered under load, and both are easy to miss if the benchmark doesn't report which precision format was in use. Moving KV storage from BF16 down to FP8 cuts the cache's memory footprint in half. NVIDIA's own reported results show negligible accuracy loss from NVFP4 relative to BF16 and FP8 baselines across LiveCodeBench, MMLU-PRO, MBPP, and Ruler, though that finding is specific to those formats and those benchmarks rather than a claim that generalizes across every workload.
A two-level accumulation strategy writing to FP32 registers substantially recovered the accuracy lost by the capacity numbers' quantization approach. Either way, it's a measured regression on a production-relevant task format, not a hypothetical edge case, and it came from NVIDIA's own publication on vLLM's blog. The practical consequence is that FP8 KV cache can look fast and accurate in a short-context benchmark and then quietly fail at long context once real load pushes context length up, which is precisely the failure a sustained-load benchmark needs to be built to catch. That April 2026 vLLM blog post was itself bylined by contributors from AWS and Red Hat AI.
TurboQuant takes a different approach: it compresses KV cache storage down to 3 to 4 bits and dequantizes back to BF16 before running attention. That cuts memory pressure but doesn't speed up the attention computation itself the way hardware-native FP8 Tensor Core operations do. Most published TurboQuant results come from small models tested on short-context benchmarks, conditions that don't put real pressure on the quantization scheme. As the vLLM blog post describing the method puts it, TurboQuant compresses only the KV cache storage to 3-4 bits and dequantizes back to BF16 for the attention computation. A benchmark that reports TTFT or ITL figures without stating the KV precision format in use is leaving out a variable that can shift both numbers substantially, and that gap widens at the long context lengths where KV cache memory starts to rival parameter memory in size. Any comparison across deployments, or across vendor claims, needs the precision format disclosed alongside the latency numbers, or the comparison isn't really comparing the same thing.
What a disciplined, load-aware measurement methodology requires
Everything in the sections above points to the same conclusion: a reproducible measurement of TTFT and ITL under sustained load demands explicit choices about workload shape, concurrency profile, metric decomposition, and disclosure, and none of those choices come with a safe default.
Metric decomposition comes first. IntuitionLabs published this metric-decomposition analysis. TTFT, TPOT/ITL, end-to-end latency, throughput, and goodput need to be measured and reported as separate quantities, because a single tokens-per-second figure flattens distinctions that matter for actually diagnosing where a system is struggling. Goodput, throughput counted only for requests that meet a defined latency service-level objective, is the most honest of the aggregate numbers, since it penalizes a system for hitting high throughput by violating the latency contract it's supposed to honor. Gains in throughput, TTFT, TPOT, memory footprint, and accuracy all need to be checked against that same workload and the same latency constraint.
Percentile reporting comes next, and it isn't optional. Every latency metric needs P50, P90, and P99 reported alongside it, because the AIMulitple data from August 2026 shows a median that looks entirely fine sitting next to a P90 that would disqualify the system from production use. Reporting only the median, as many vendor benchmarks still do, hides exactly the tail behavior that sustained load is most likely to produce. IntuitionLabs states that serving benchmarks should report p50, p95, and p99 rather than a single average.
Under sustained concurrency, TTFT and ITL do not degrade uniformly: they degrade through three distinct mechanisms that compound each other. It's measuring something narrower, dressed up to look like the real thing.
Sources
- LLM Latency Benchmark by Use Cases in 2026
- Measuring AI Serving Performance: Latency and Throughput | IntuitionLabs
- test(llm-router): measure sustained token-generation capacity and latency · Issue #1230 · NVIDIA/nvcf
- InferenceBench: A Benchmark for Open-Ended LLM Inference Optimization by AI Agents
- LLM Inference Tokens Per Second: 2026 Benchmarks &... | Lyceum Technology
- LLM inference latency: TTFT, tokens per second, and what to measure | Engineering | ClickHouse Resource Hub | ClickHouse
- Understand LLM latency and throughput metrics | Anyscale Docs